devtake.dev

#ai-models

RSS
OpenAI's GPT-6 Astra launch card, showing a white spiral galaxy of stars on black with the words GPT-6 and Astra set on either side.
AI·

OpenAI shipped GPT-6 Astra with an AGI claim and a build that refuses exploit work

Brockman called it the AGI era. Astra shipped to Daybreak enterprises first at $10/$50 per million tokens, and the cyber build stays gated.

Anthropic's launch card for Claude Fable 5.1 and Claude Mythos 5.1, white serif text over a pale blue sky with clouds and a daytime moon.
AI·

Six Claude 5 models in twelve weeks. Fable 5.1 is the first to watermark its output.

Anthropic's Fable 5.1 doubles a science benchmark and cuts cache reads 75%. Independent tests measured tasks costing up to 3x more than Fable 5.

Aerial photograph of the Pentagon's five concentric rings and central courtyard, ringed by parking lots and highway interchanges on a bare winter day.
Policy·

The Pentagon added ChatGPT and Grok to its own AI portal for 3 million staff

GenAI.mil now serves OpenAI's ChatGPT Mil and Starshield AI's Grok for Government at IL5, nine months after Google's Gemini opened the portal.
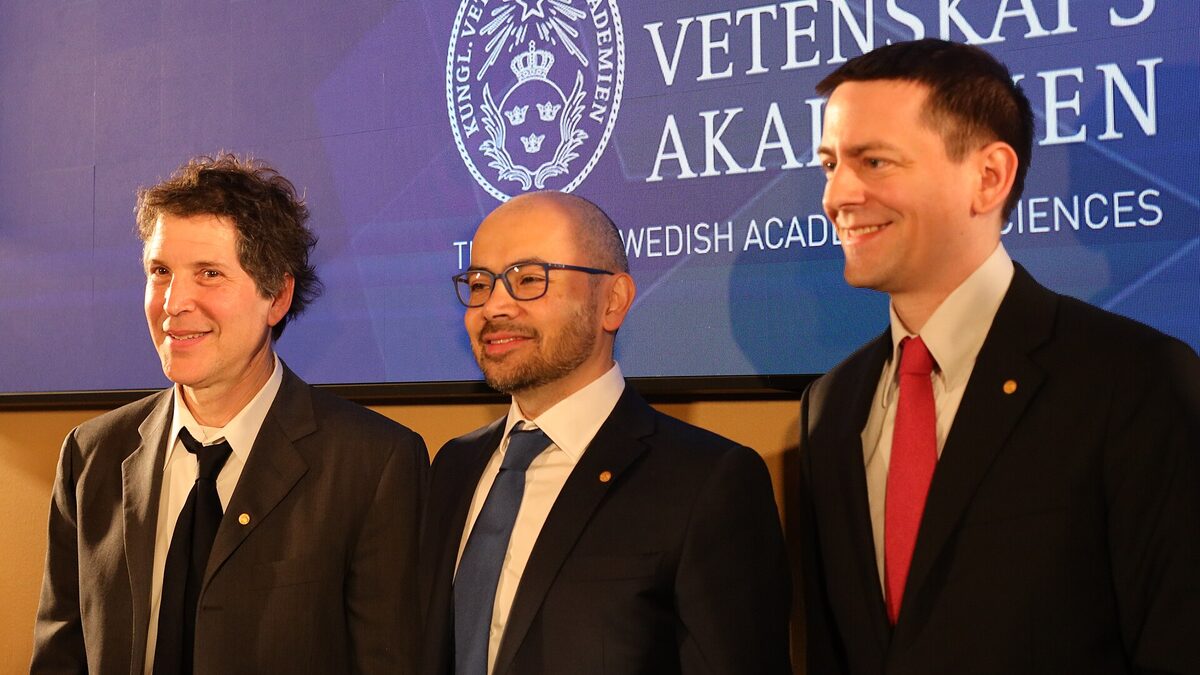
Demis Hassabis stands between David Baker and John Jumper in front of a Royal Swedish Academy of Sciences backdrop at the 2024 Nobel Prize conference
AI·

Google moved Demis Hassabis out of the DeepMind CEO seat. Koray Kavukcuoglu now runs Gemini.

Sundar Pichai made Hassabis chair of Google DeepMind and Alphabet chief scientist. Koray Kavukcuoglu takes the Gemini org, and Jeff Dean is leaving.
The Meta wordmark below the company's blue infinity-loop logo on a white background
AI·

Meta's Muse Code: a terminal agent built for repos most devs never touch

Meta's Muse Code is in beta on macOS and Linux, priced at $1.25 per million input tokens. Meta's own benchmarks put it behind Claude Opus 5.
An Alibaba Group office building with the company's orange logo sign above the entrance and cars parked outside.
AI·

Alibaba's Qwen3.8-Max beats Fable 5 on Terminal-Bench, and the weights go public next week

Qwen3.8-Max is a 2.4-trillion-parameter MoE that tops Claude Fable 5 on Terminal-Bench 2.1 and trails it badly on SWE-bench Pro. It's the first open Max-tier Qwen.
The GitHub social preview card for the openai/ten-proofs repository, described as Lean certificates accompanying proofs in mathematics and theoretical computer science, showing 386 stars and 35 forks.
AI·

Ten decade-old math problems fell to an unreleased OpenAI model, for about $2,000 of tokens each

OpenAI published ten results in math and theoretical CS from an internal build of Astra, with Lean 4 certificates for every proof. What that verification does and doesn't settle.
The Hugging Face model page card for deepseek-ai/DeepSeek-V4-Flash-0731, showing the DeepSeek whale logo and the repository name
AI·

DeepSeek's new 304B agentic model now runs on a single 128GB workstation

Salvatore Sanfilippo repacked DeepSeek V4 Flash into a lossless MXFP4 GGUF that streams from SSD at over 20 tokens a second. The hardware bill, and where hosted still wins.
Anthropic's Claude Opus 5 announcement artwork: a large numeral 5 formed from an arrangement of vintage speckled bird-egg illustrations on a cream background.
AI·

Claude Opus 5 nears Fable 5's frontier intelligence at half the price

Anthropic shipped Claude Opus 5 at the same $5/$25 per million tokens as Opus 4.8. It nears Fable 5's intelligence at half the cost, with new effort and fallback controls.
Google Gemini key art showing the 3.6 Flash, 3.5 Flash-Lite, and 3.5 Flash Cyber model names
AI·

Google shipped three Gemini Flash models but held back its flagship Pro

Google released Gemini 3.6 Flash, 3.5 Flash-Lite, and a cyber specialist, and teased Gemini 4. The 3.5 Pro tier it promised in May still isn't out.
Two pelicans face each other with crossed beaks on dark water, mirrored in the surface, a nod to the informal 'pelican on a bicycle' LLM benchmark
AI·

Kimi K3 trades blows with Anthropic's Fable, and Moonshot is opening the weights

Kimi K3, GLM 5.2 and DeepSeek V4 put open-weight AI next to the frontier this month. What each model is good at, and why the benchmarks mislead.
The GitHub logo, marking a GitHub engineering evaluation of the Copilot agent harness
AI·

GitHub ran four frontier models through Copilot's harness. None won every task.

GitHub benchmarked Copilot's agent harness against Claude Code and Codex CLI on five tests. The token savings are real, and the best model depends on the task.
Anthropic Claude Sonnet 5 announcement graphic
AI·

Claude Sonnet 5: cheaper agents on paper, until you count the new tokenizer's tokens

Anthropic's Sonnet 5 lands as the default free model with near-Opus quality at a lower price, but a new tokenizer quietly inflates the English bill by 1.4x.
Anthropic's Claude branding on a soft gradient panel, used to illustrate the redeployment of Fable 5 after export controls were lifted.
Policy·

The US lifted its export ban on Anthropic's Fable 5. The model returns Wednesday.

The Commerce Department cleared Claude Fable 5 and Mythos 5, ending an 18-day export-control freeze. Anthropic redeploys Fable 5 globally on Wednesday with tighter safeguards.
The north facade of the White House in Washington under a clear sky.
Policy·

The White House told OpenAI to gate GPT-5.6. Frontier models now need government sign-off.

The Trump administration asked OpenAI to limit GPT-5.6 to trusted partners, with the government vetting access customer by customer. Here's what that gatekeeping means.
Google Gemini chat interface shown on screen
AI·

Google reportedly delays Gemini 3.5 Pro to July to keep tuning the model

Google has pushed its frontier Gemini 3.5 Pro to July while Flash already ships, according to Business Insider. Here's what slipped and why it matters.
Abstract render of an AI neural network over rows of data-center servers
AI·

Anthropic wants Congress to punish Alibaba over 28.8 million Claude queries

Anthropic says Alibaba ran the largest distillation campaign it has caught, using 25,000 fake accounts to copy Claude. Here is what that claim actually means.
Benchmark comparison card for GLM-5.2 showing it as the leading open weights model
AI·

GLM-5.2 was trained on Huawei chips, not Nvidia. The open weights beat GPT-5.5 on coding.

Zhipu AI's GLM-5.2 is a free-to-download model trained without Nvidia silicon. Here's what the benchmarks claim and why developers should care.