
AI·
Nvidia's $12.9 billion bid for Hugging Face would also buy the llama.cpp team
Hugging Face turned down Nvidia at a $7 billion valuation last year. The reported price is now $12.9 billion, and the ggml maintainers come with it.
Hugging Face turned down Nvidia at a $7 billion valuation last year. The reported price is now $12.9 billion, and the ggml maintainers come with it.
Qwen3.8-Max is a 2.4-trillion-parameter MoE that tops Claude Fable 5 on Terminal-Bench 2.1 and trails it badly on SWE-bench Pro. It's the first open Max-tier Qwen.
Salvatore Sanfilippo repacked DeepSeek V4 Flash into a lossless MXFP4 GGUF that streams from SSD at over 20 tokens a second. The hardware bill, and where hosted still wins.
Kimi K3, GLM 5.2 and DeepSeek V4 put open-weight AI next to the frontier this month. What each model is good at, and why the benchmarks mislead.
Zhipu AI's GLM-5.2 is a free-to-download model trained without Nvidia silicon. Here's what the benchmarks claim and why developers should care.
The Commerce Department paused adding DeepSeek and 100+ Chinese firms to the Entity List. Here's what the export-control blacklist does and why DeepSeek was spared.
A popular Hacker News how-to walked through a fully local coding agent on Apple Silicon. Here's the realistic 2026 stack: runner, model, and harness.
Needle is a 26M-parameter function caller distilled from Gemini 3.1 Flash-Lite. The Simple Attention Network drops MLPs and runs at 6,000 tok/s prefill on edge silicon.
Arcee released Trinity-Large-Thinking on April 1: a 399B-param sparse MoE with 13B active, Apache 2.0 weights, $0.88 per million output tokens, and PinchBench just behind Opus 4.6.
OpenAI released Privacy Filter on April 22 as an open-weight on-device model for masking eight types of PII. F1 of 96%. Runs in a browser. Here's the catch.
DeepSeek shipped V4-Pro and V4-Flash under MIT on April 24. V4-Pro hits 80.6% on SWE-bench Verified. V4-Flash is $0.14 in / $0.28 out.
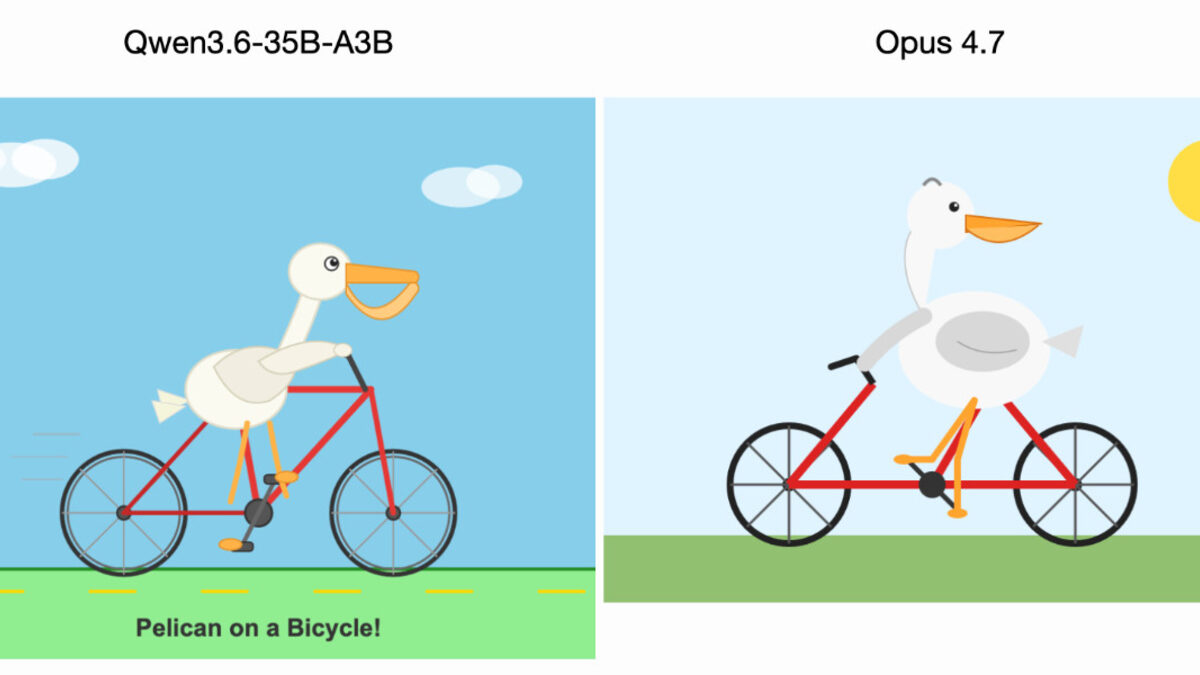
Alibaba's Qwen 3.6-35B-A3B is a 35B-param mixture-of-experts with only 3B active. Apache 2.0, runs on consumer GPUs, and it's already winning real tasks.